New Squidex Features

Last Update: Apr 12, 2026

2026

Searchable string fields and resolvable comments

You can now mark string fields as search fields, which adds them to full text search with a simple contains search, so lookups on titles, slugs or codes behave the way you expect. Comments have also grown up: you can resolve them and switch to a view that shows resolved comments as well.

Schemas gain User Info fields that hold API keys for authentication, and scripting gets a method for making specific HTTP requests along with a flag to ignore HTTP errors. The management UI can now be disabled entirely if you only want to expose the API.

The backend moves to .NET 10, the frontend to Angular and Node v21, and German is available as an additional interface language. Alongside that come a responsive menu for content fields, a wider left panel on demand, improved form rows and a set of accessibility corrections, plus fixes to the OpenAPI spec, the rich text editor, fullscreen mode and the query system.
2025

AI-assisted schema generation and FerretDB support

You can now generate schemas with AI support directly in the UI, which gives you a starting point for a content model instead of defining every field by hand. Creating apps has also moved into a new dialog, and the management UI has received a number of smaller improvements along with an update to the current Angular version.

On the backend, Squidex now works with FerretDB, and likely with CosmosDB and DocumentDB as well, widening your options for the database layer. The content API gains a new inline filter and supports the X-Fields header on all endpoints, so you can restrict responses to the fields you actually need.

This release also fixes several issues in rules: the prepare step and error handling for scripts, URL properties of steps that are now plain strings, and the status display for cancelled events.


Connection pooling for SQL-backed deployments

If you run Squidex on a SQL database, DbContext instances are now created through pooling. This reduces the overhead of setting up a new context for every operation and helps keep resource usage more predictable under load, without any change to how you configure your database.

The rest of the release focuses on the rule editor in the management UI. Validation of If-steps in a rule flow now behaves correctly, so invalid conditions are reported when you edit them. Icons in the flow editor are rendered at the right size, and the button to enable or disable a rule uses the correct background color.


Flows replace rule actions with per-attempt tracking

Rules now run on a new flow system that replaces the old way of defining rule actions. Existing rules keep working and are migrated to flows automatically, and each action attempt is tracked separately so you can see exactly where a rule failed. Because the database structure changed, existing rule logs cannot be migrated. If you still have failed items in your log, wait with the update until your rules succeed again, or disable the rule enqueue in the administration section to halt execution until everything has been processed.

Rules also gain a new cron job trigger, with a minimum interval of four hours between jobs. On the API side, JSON endpoints now support content compression, and sensitive configuration values are redacted in the log.

In the UI, AI chat conversations are kept and restored across sessions, autocompletion is disabled for password fields, and there are fixes for the expanded editor mode, the browser tab title, star control defaults and the onboarding system. For custom authentication servers you can now disable the OIDC profile scope.


SQL database support for MySQL, Postgres and SQL Server

Squidex can now store its data in SQL databases. This release adds support for MySQL, Postgres and SQL Server alongside the existing MongoDB storage. The implementation is covered by an extensive test suite, but it is still an early version, so treat it as experimental and evaluate it carefully before moving production data.

To keep the container image smaller, ImageMagick and Kafka support are no longer included in the official Docker image. ImageMagick is no longer required because ImageSharp handles all relevant image formats, and you can also use the dedicated image resize server. If you build your own container or binaries, both can be re-enabled with the INCLUDE_MAGICK and INCLUDE_KAFKA define constants, for example dotnet build -p:DefineConstants=INCLUDE_MAGICK.

The release also fixes full-text search integration for Azure Search and Elastic Search, ensures events can be replayed once the end of the Mongo commit log is reached, and redirects users to the specified URL after logout.


Map identity provider errors to user-friendly messages

Squidex can now translate errors returned by external identity servers into messages that make sense to your users. Instead of surfacing a raw provider error, you can configure a mapping so that a failed login shows text you control, which is useful when you connect Squidex to an OIDC provider that returns technical or provider-specific error codes.

This release also fixes a regression in the management UI: autocompletion fields are clickable again, so you can pick a suggestion with the mouse instead of having to use the keyboard.


2024

Custom content indexes and new scripting extensions

You can now define indexes for your content collections through both the API and the UI, which lets you tune query performance for the fields your applications actually filter and sort on. Queries can also specify a collation, so text comparisons follow the rules of the language you work with, and schemas can now be deleted permanently through the API.

Scripting gains two extensions: you can query content from within scripts, and you can send non-JSON bodies in outgoing requests. On the telemetry side, Squidex ships exporters for OpenTelemetry logs and metrics, so you can forward both into your existing observability stack.

The UI has been simplified in several places, including the login screen and the asset and reference content editors, and comments now offer autocompletion for mentions. Fixes cover the OpenAPI spec for file uploads, meta key detection when opening content in a new tab, and prefix detection in custom queries.


More control over default value enrichment in content queries

Content queries now give you finer control over how items are enriched. A new header flag lets you turn off enrichment with default values entirely, while another flag extends enrichment to required fields, so you can decide which shape the API returns for your clients. Query responses also no longer return null statuses, and fields whose names collide with meta fields are delivered correctly.

On the editing side, the code editor is now editable in the markdown mode of the rich text editor, and clipboard behavior in the rich text editor has been fixed. Editor extensions receive a new event when the context changes, and the embed SDK supports data attributes for Squidex tokens.

The rest of the release is made up of UI fixes, including autocompletion in the code editors, filter handling in the query dialog and when selecting references, and correct navigation from the content page back button.


AI article and image generation with OpenAI and DALL-E

Squidex can now generate full articles with embedded images as well as standalone images using OpenAI and DALL-E. Responses from the AI tools are streamed, and the chat shows you which tools were used for a result.

On the content side you get new update statements for Upsert, Update and Patch, a menu item to open a content item in a new tab, and fixes to the inline editor, cursor positioning and workflow handling for draft versions. The filter UI now supports the NOT operator, and GraphQL uses a proper JSON type so you can run mutations with variables. Assets expose new SVG metadata (svgWidth, svgHeight, viewBox), and the file hash is optional in MongoDB for compatibility with older installations.

The management UI has been updated to Angular 18 with better error messages for background jobs and navigation that keeps the browser history intact. Identity gains a prompt parameter for OIDC and custom OIDC servers for teams, and Docker images are now built for ARM.


Job completion notifications and Rich Editor fixes

Squidex now notifies you when a job has completed, so you no longer have to keep the jobs page open to find out whether a long running task such as a backup has finished.

The Rich Editor received two fixes: overlapping class names are now allowed, and the word and character counts are calculated correctly. On the content side, full text handling now works with large content IDs, and error responses from the API keep field names exactly as you defined them instead of normalizing them. Permanent app deletion also registers its deleter correctly again.

This release additionally updates the NSwag and OpenIdDict dependencies used for API documentation and authentication.


A unified job system for rules and backups

Squidex now uses a single job system for background work. Rules and backups share the same infrastructure, which makes their behaviour consistent and gives future background jobs a common foundation to build on.

This release also fixes two smaller issues. Assets that were stored without a total asset size are now deserialized correctly, so they no longer fail to load. In the comments, you can reply to any comment instead of only to your own, which makes discussions in the Management UI easier to follow.


2022

Blur Hash for assets

The scripting got a new feature to calculate the blur hash now. This can be useful when you want to provide a nice placeholder while the real asset is still loading. Read more about that at: https://blurha.sh/


Editor SDK for your Website

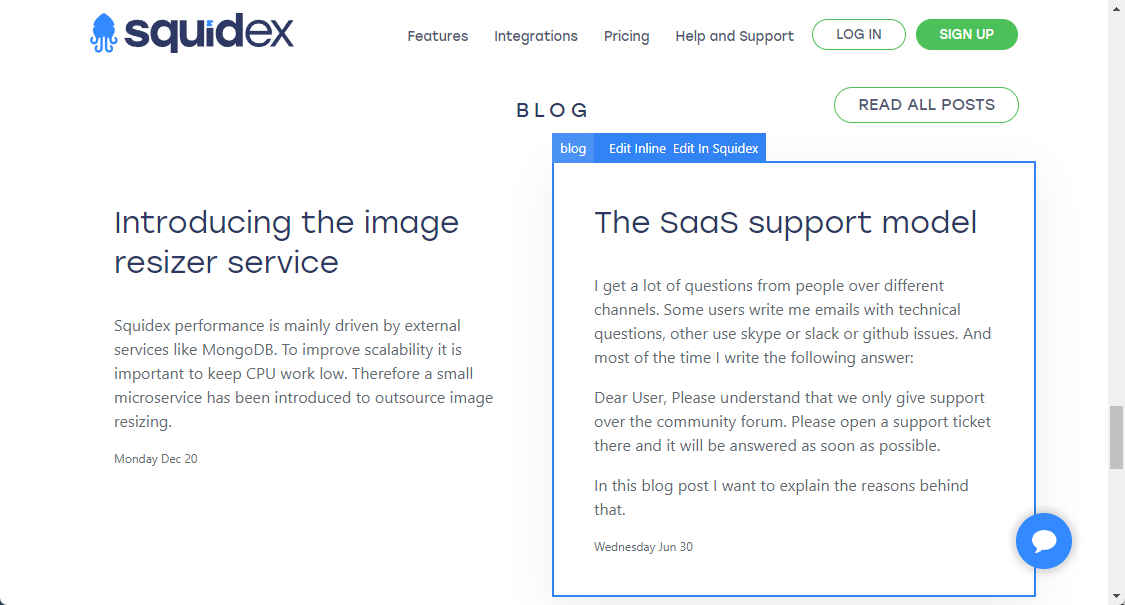
A brand new SDK has been published that can be added to your website. When the SDK is installed you can annotate contents that have been queried for Squidex and the SDK highlights these content items to your editors. Therefore your editors will always know where a content item is coming from and how to edit that.

You can read more about this in the Documentation.

Hightlight Content on your Website


Improved autocompletion

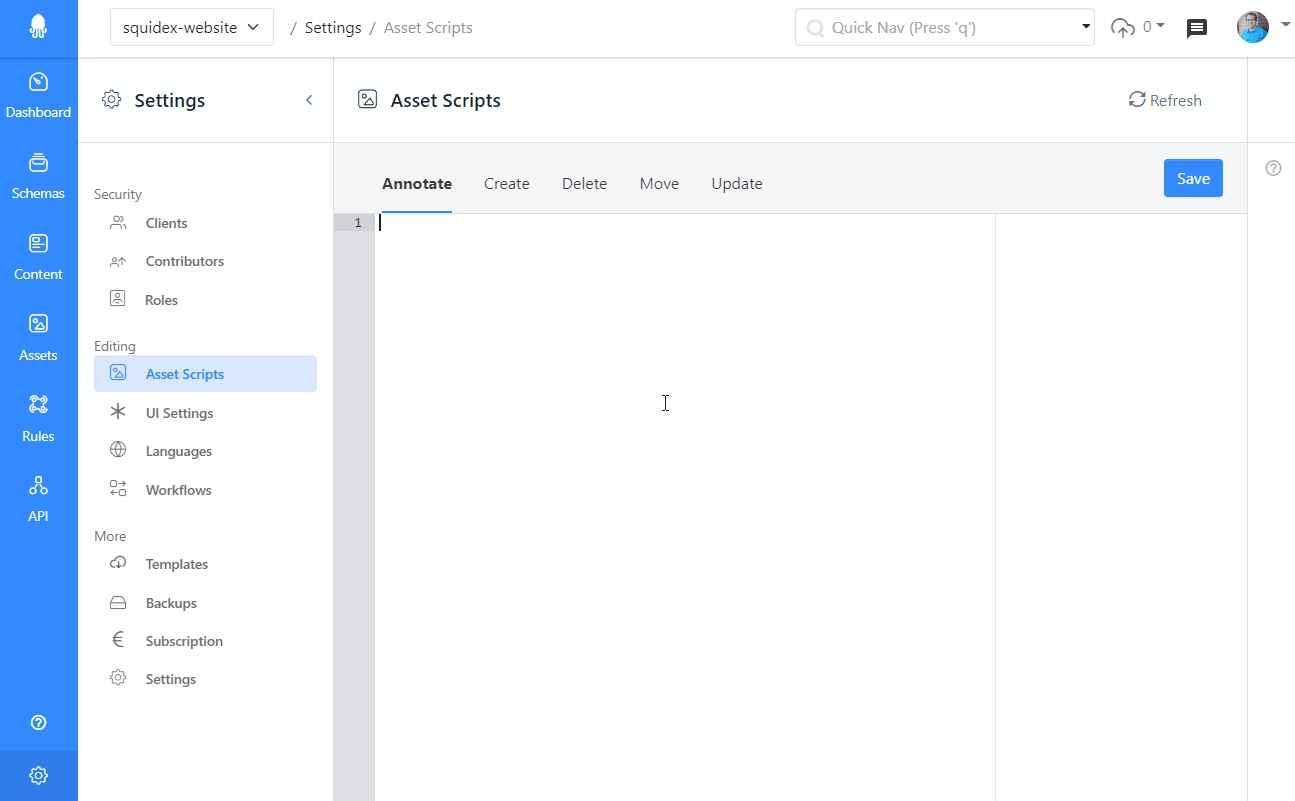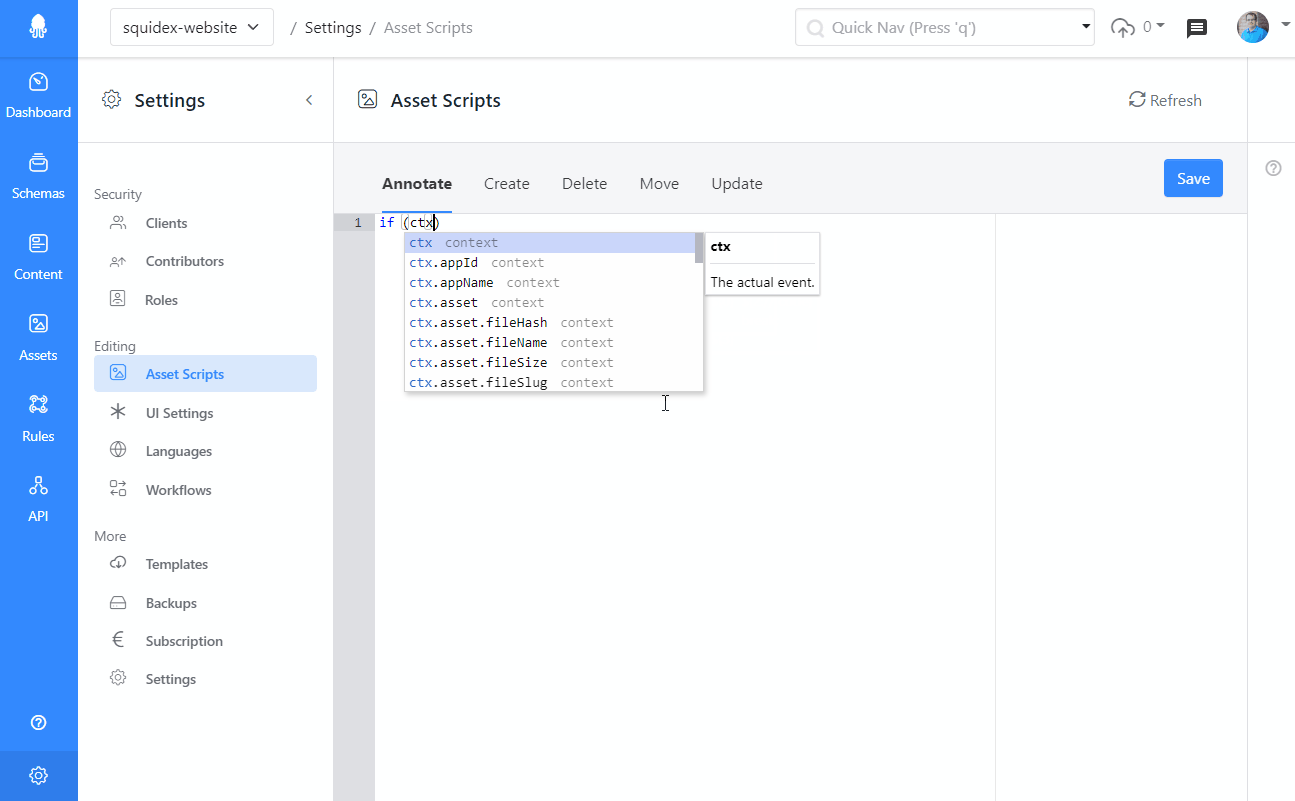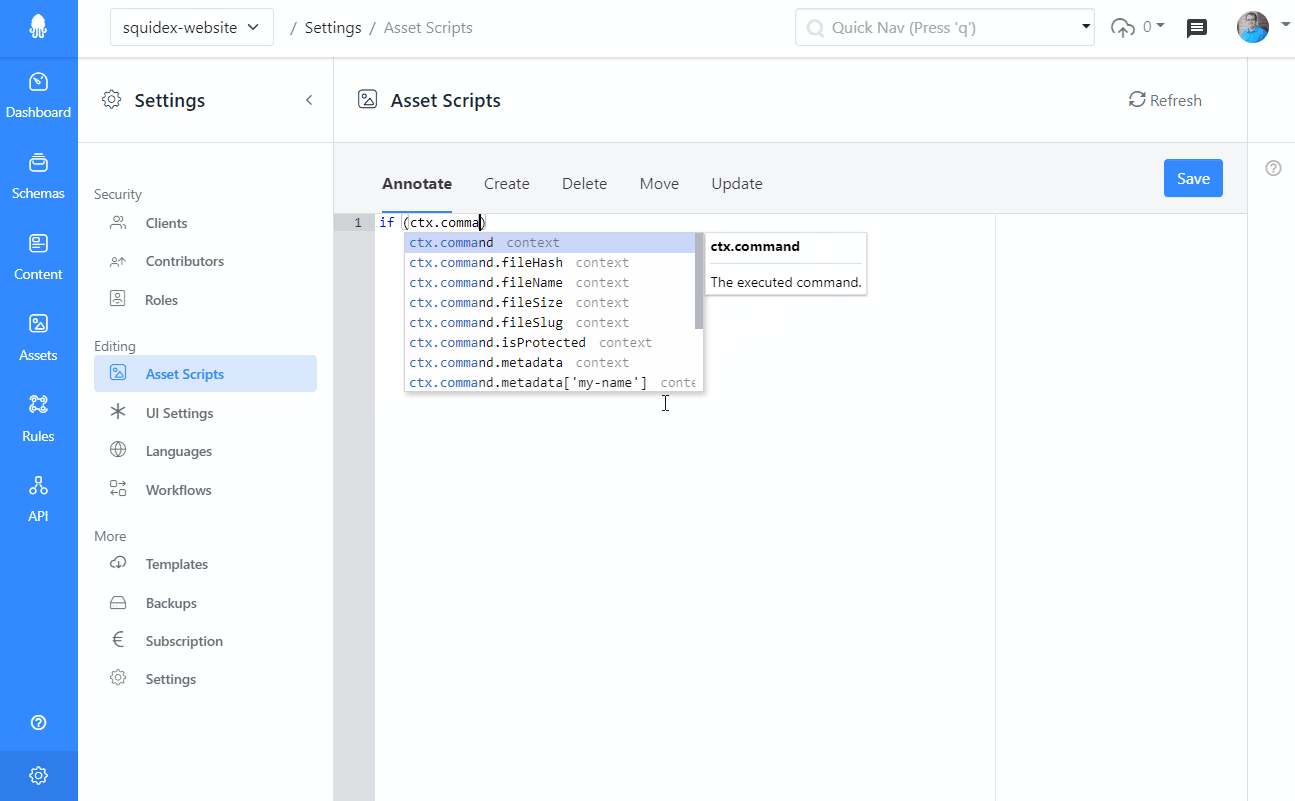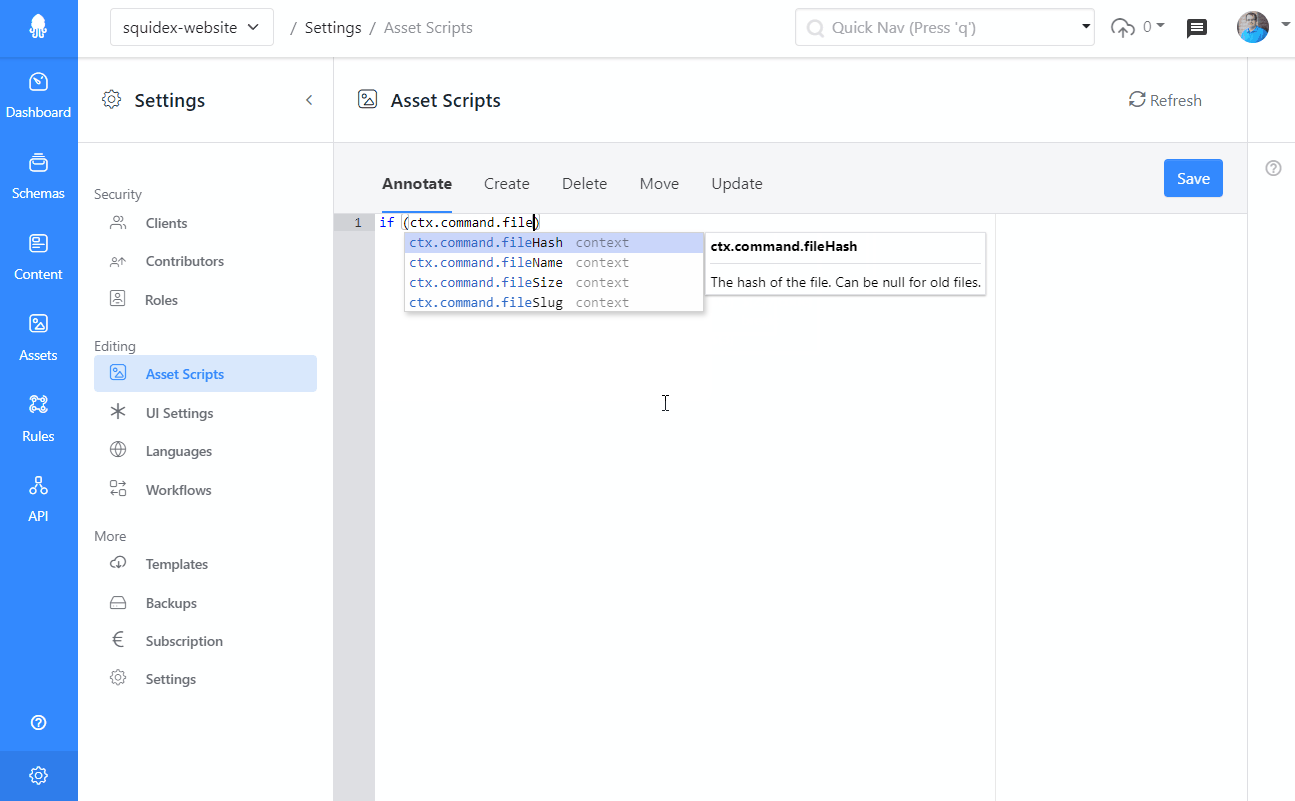
We have added autocompletion to (almost) all places where you can enter Javascript expressions or code or have improved it:

  • Schema scripts that are executed when a content is created, changed or deleted.
  • Asset scripts that are executed when an asset is uploaded, changed or deleted.
  • Rule scripts that are executed for rule actions to format the payload for requests, for example for webhook bodies.

The source of this feature is now directly generated from the code files that are used when a feature is implemented. This means that the autocompletion should be always consistent in the future and hopefully free of bugs.

AutocompletionAutocompletion


Add templates and samples to your application

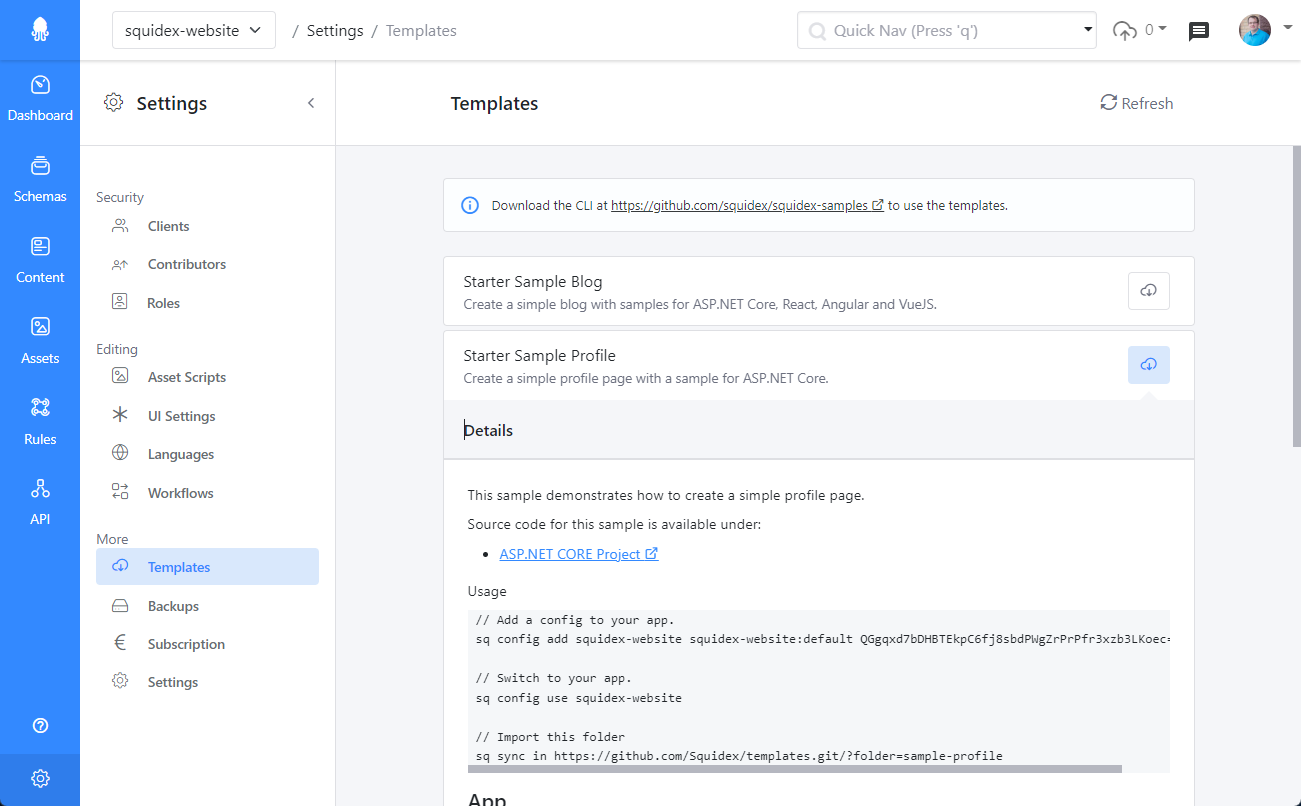
We have built a new solution to publish templates to Github repositories. These templates are available and documented with a new settings page. This template page describes what the sample contains and how to install it and also points to the corresponding sample codes. If you have installed Squidex on your own servers you can also use custom repositories.

Template ListTemplate List


GraphQL Enums

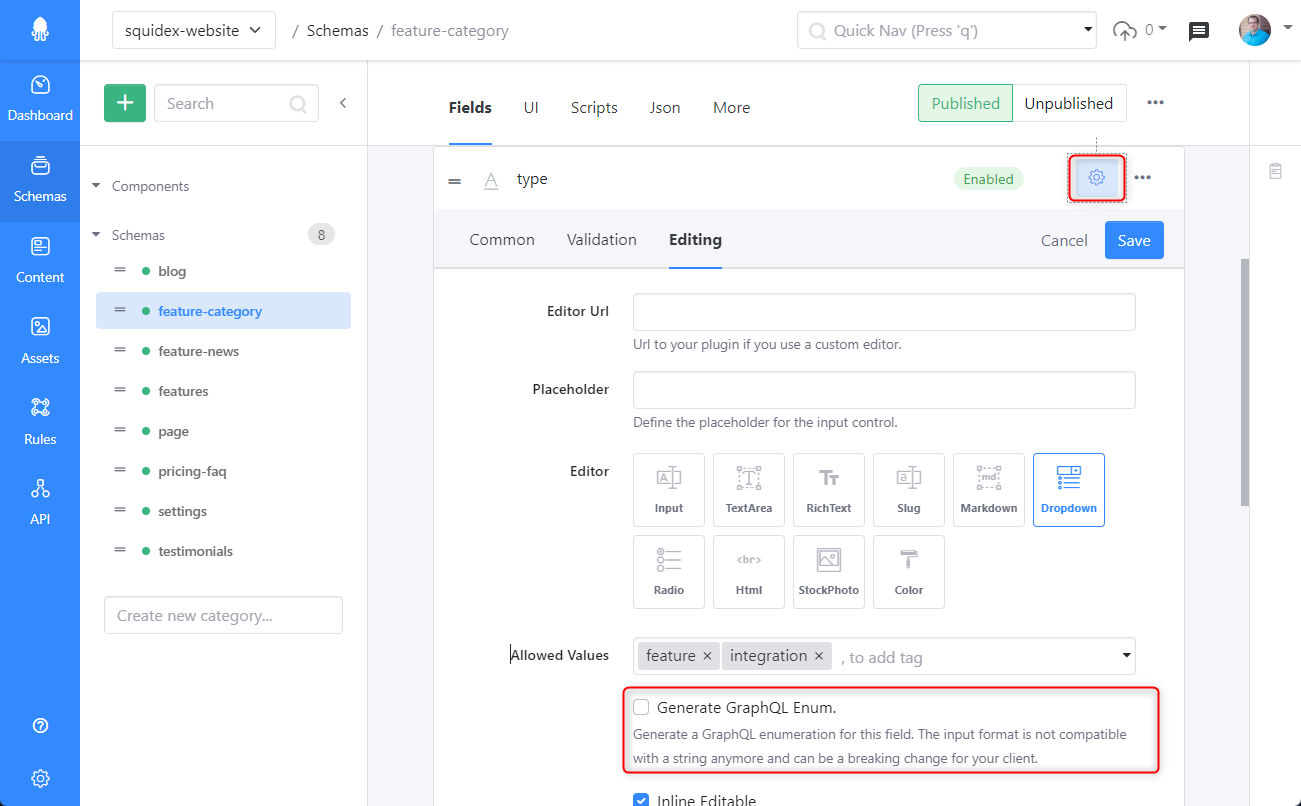
GraphQL enums are handy to have more type safety in your Client code. You can enable GraphQL enums for each String field that has a list of Allowed Values.

GraphQL EnumGraphQL Enum


Better Profile Page

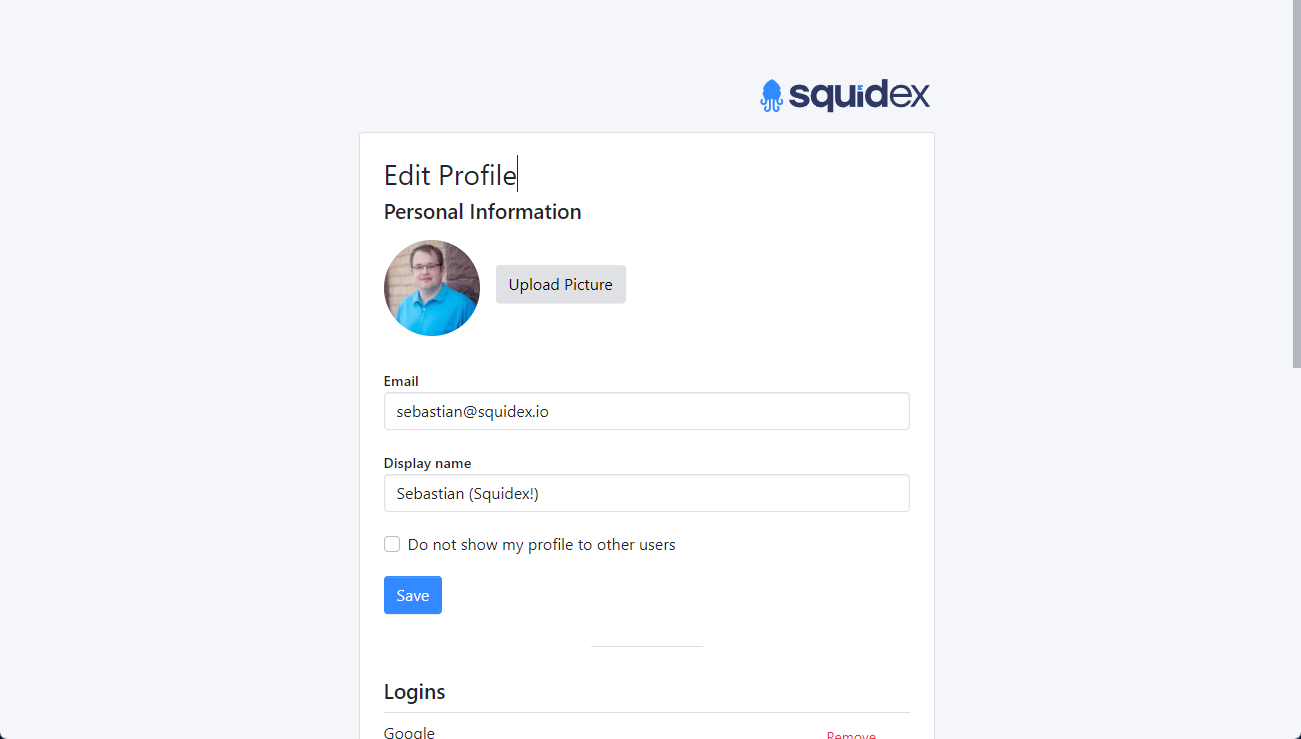
The profile page has been reimplemented to be just a normal page? Why? Because it just looks better.

New Profile PageNew Profile Page


Resizable columns

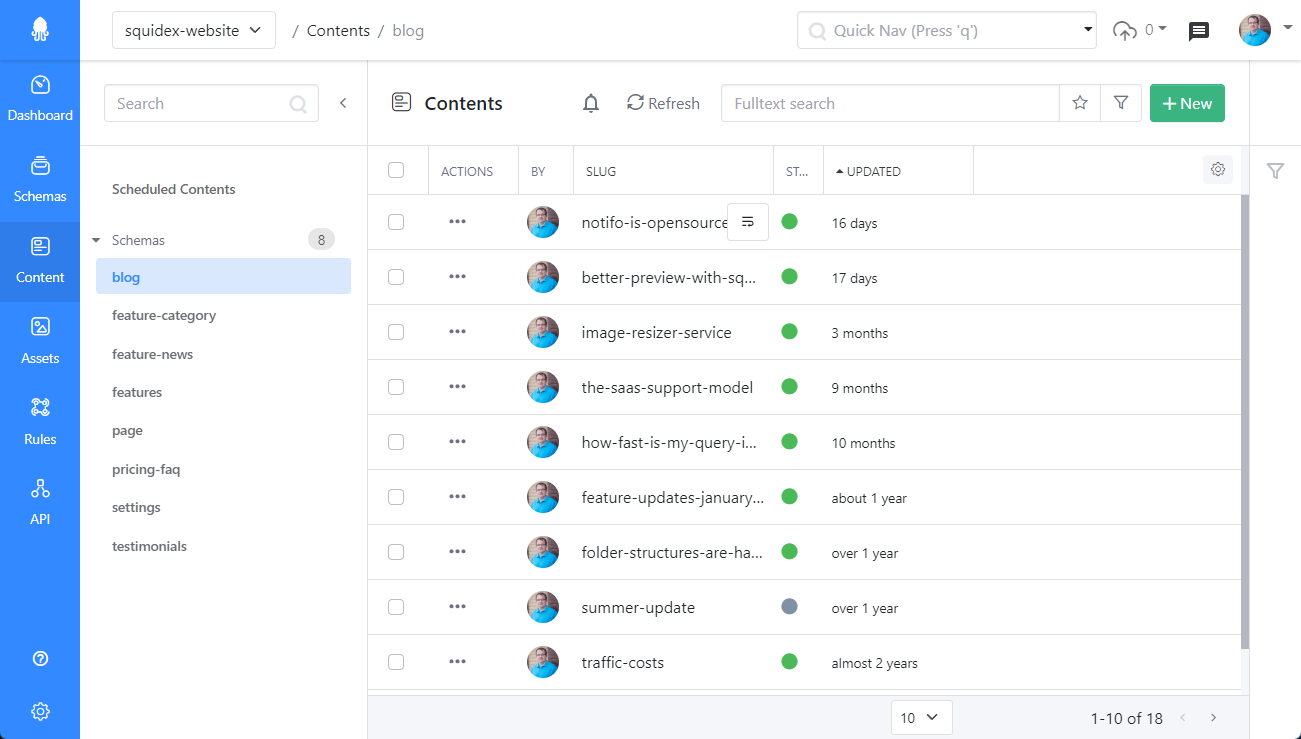
The content table has been redesigned to add two new features:

  1. You can resize custom columns now. Predefined columns like the Actions, Status have a fixed width.
  2. You can hover a column to get this small button (see screenshot below) and enable word wrapping for a column.

New Table LayoutNew Table Layout


Expanded mode for all Fields

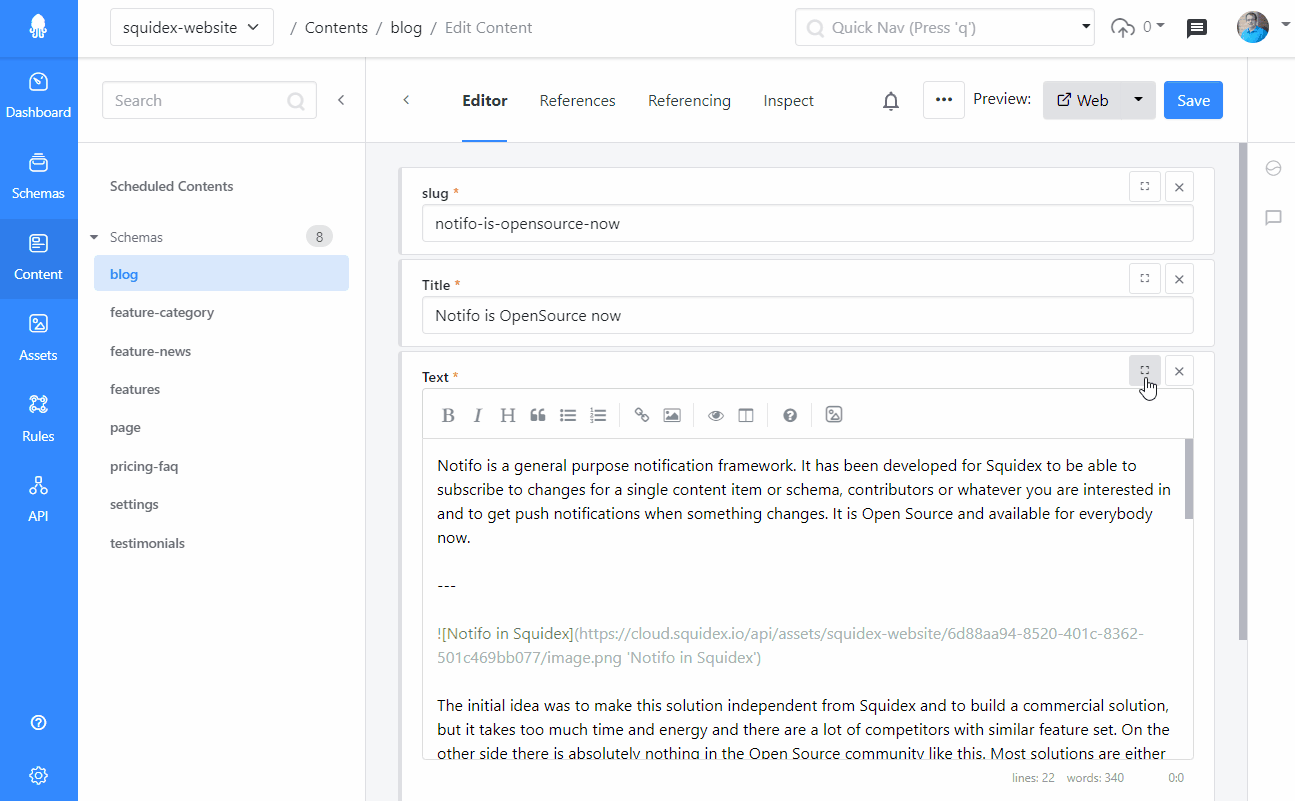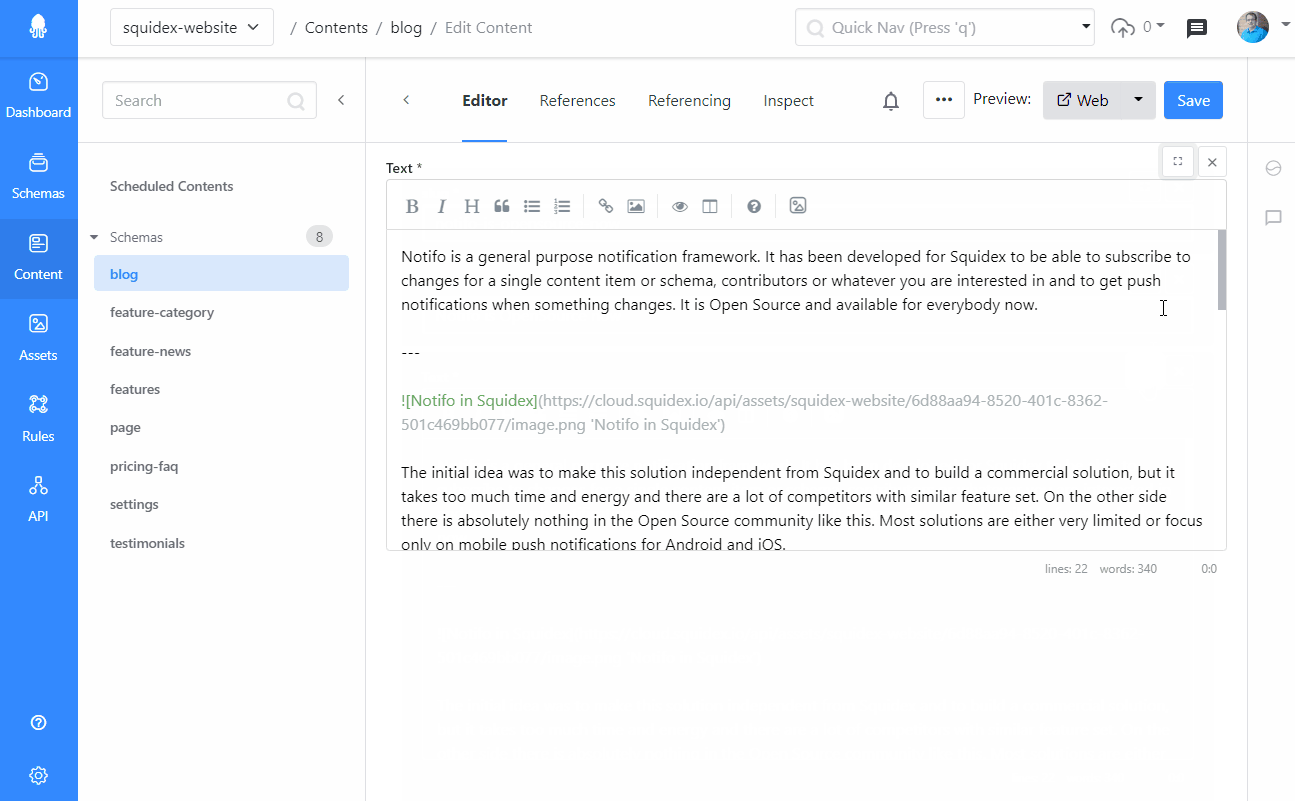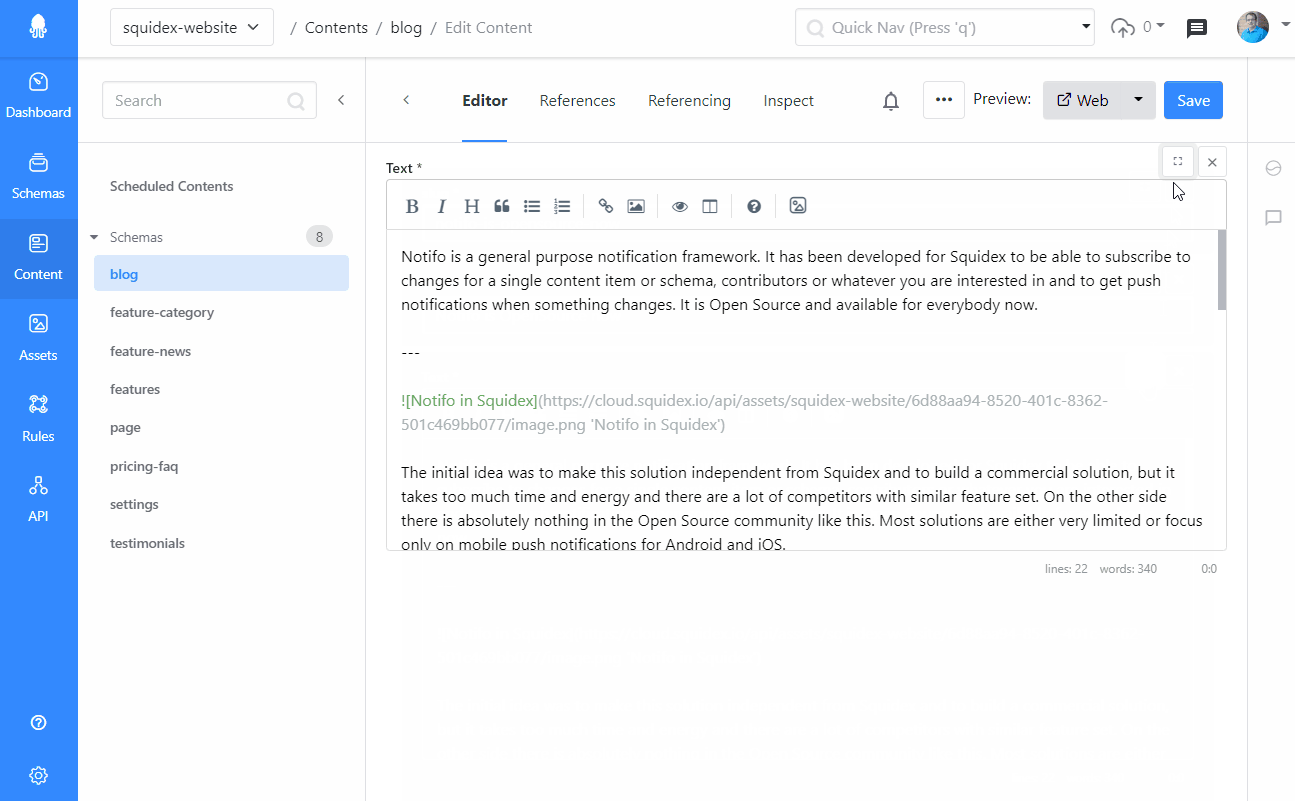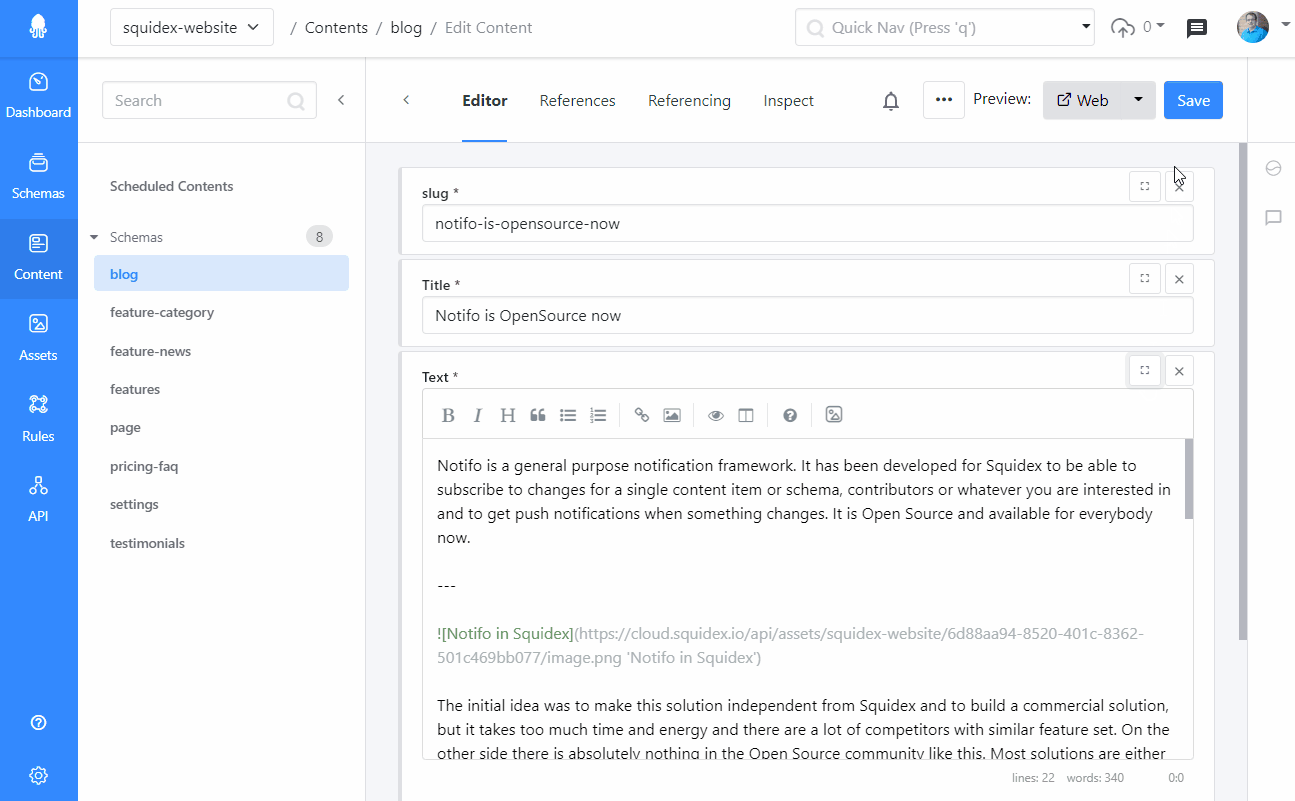
Next to each field you will see a new button now to expand the field. This is helpful if you just need more space, for example when your write a full article with the markdown editor.

Expanded ModeExpanded Mode


2021

Components

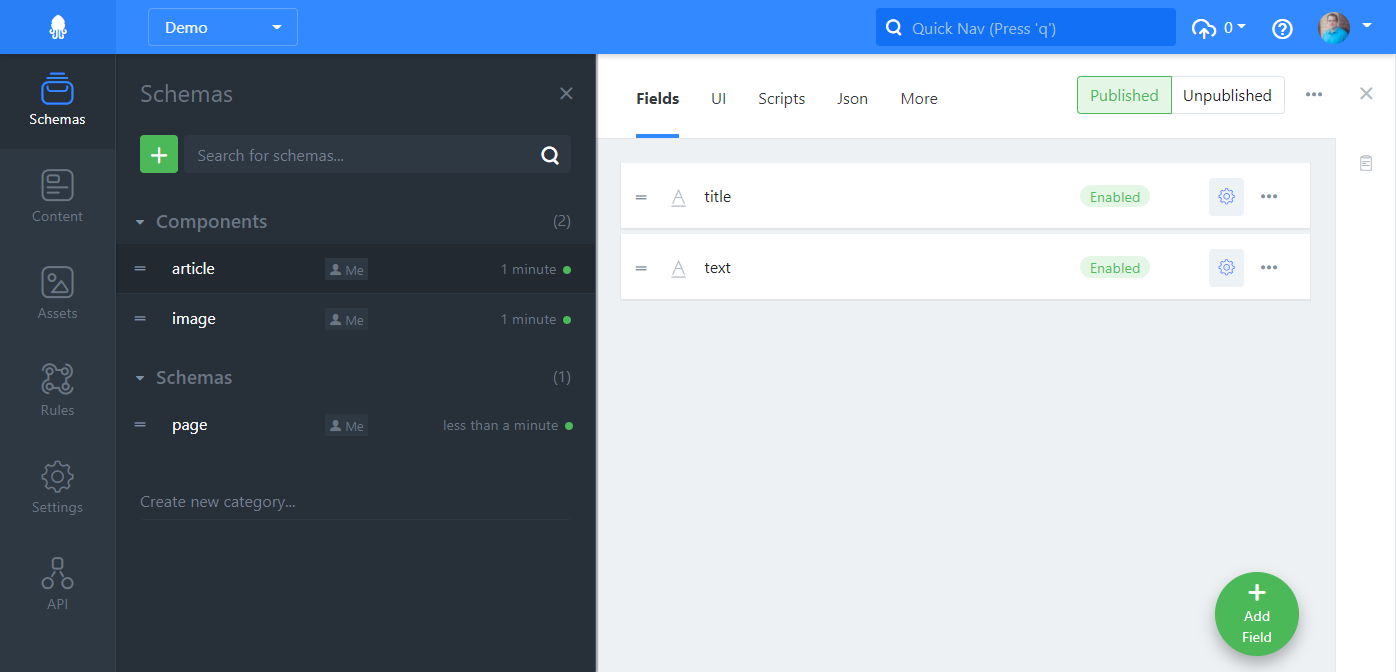
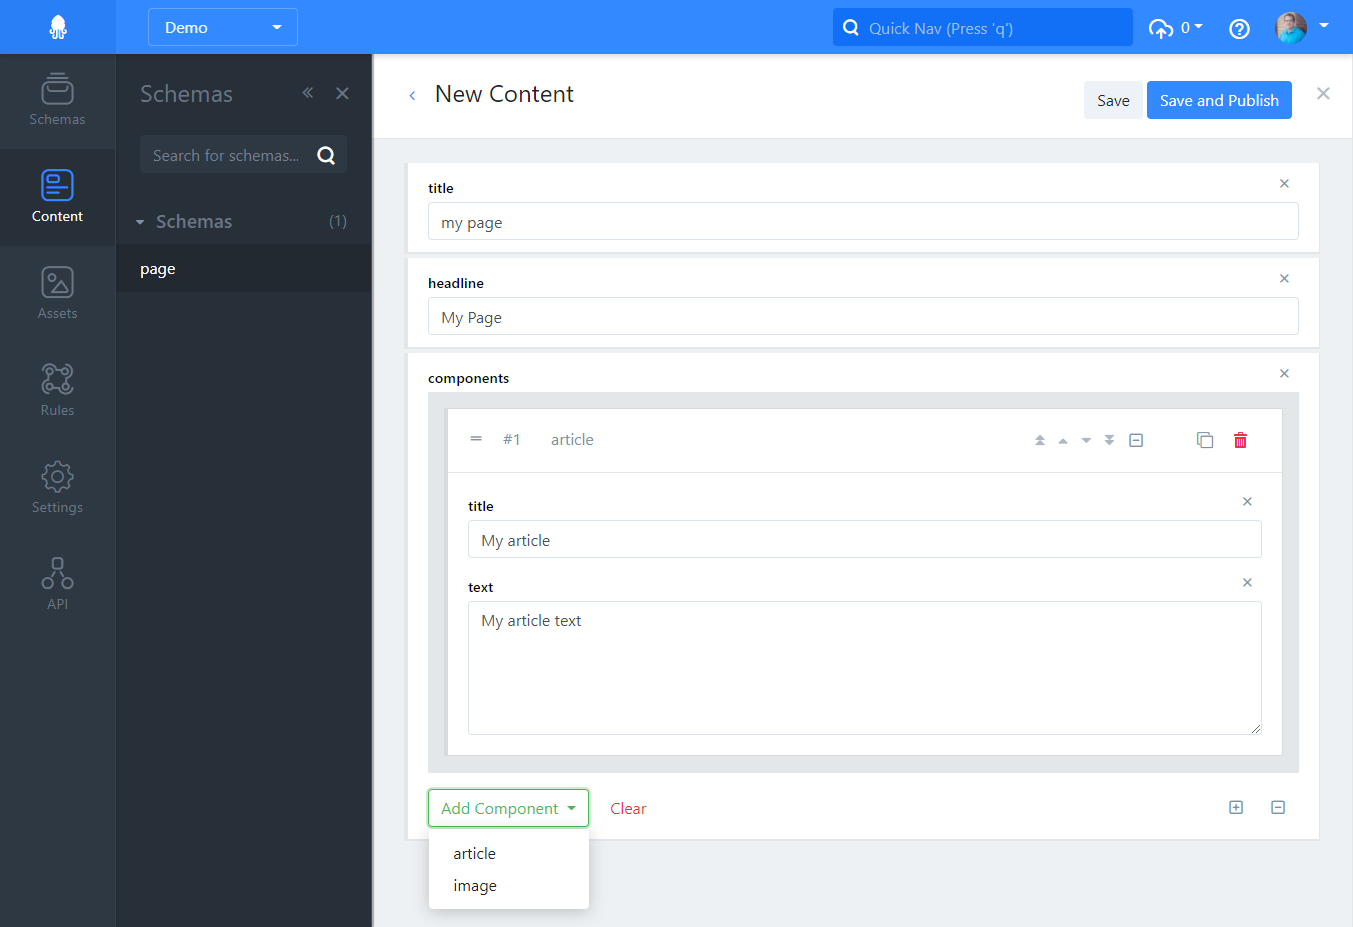
Components are a feature to embed the structure of a schema into another schema. For example you can define an page schema that holds one or multiple instances of articles or images. These schemas are created as components, so that you cannot create content directly for these schemas.

Component DefinitionsComponent Definitions

When you create a page content item you add components and define the order. This allows very flexible content structures, especially for dynamic pages such as landing pages.

Content ComponentsContent Components